Feature Flag Architecture for iOS Apps at Consumer Scale
Building iOS feature flags for offline resilience and modular architecture.
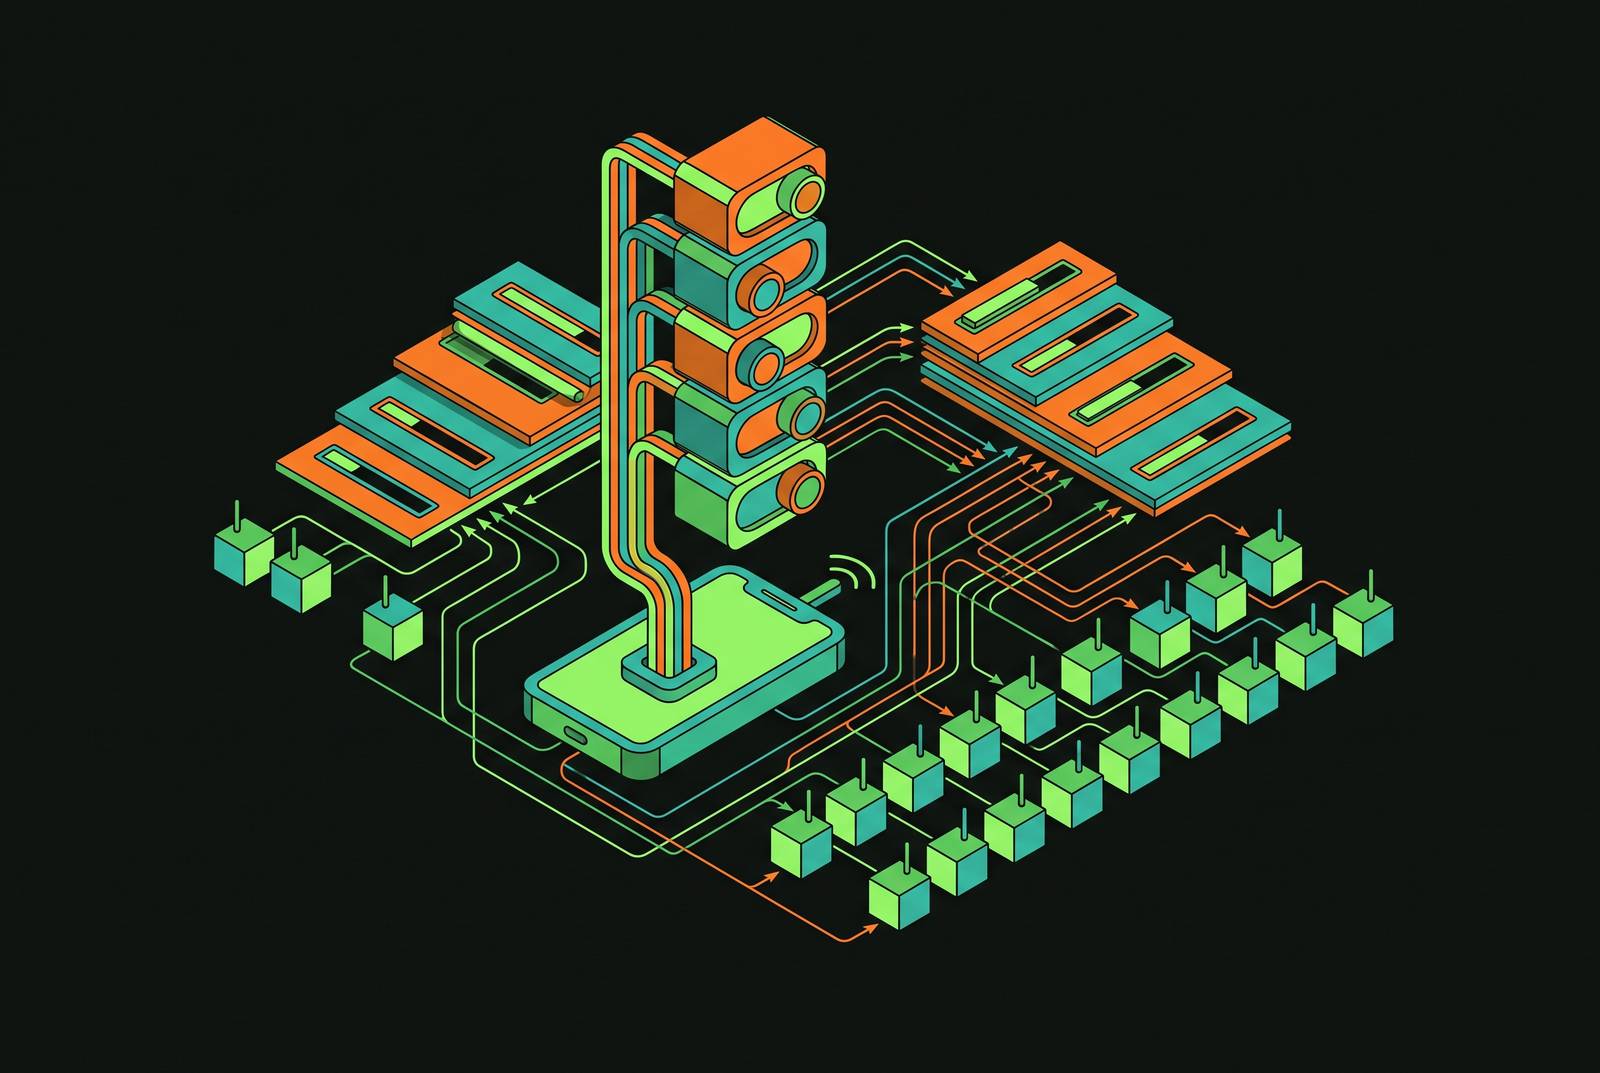
Feature flag architecture for iOS apps at consumer scale is release infrastructure. Its foundation is local, offline-safe evaluation, typed definitions, layered storage, and explicit ownership. Web-centric assumptions fail when a device loses connectivity or a change must wait for App Store review. The architecture must account for those constraints before flags spread through the codebase.
Why feature flags on iOS demand a different architectural mindset than on the web
A flag that blocks on a network call can cause flickering UI or silent failure with degraded cellular connectivity or in airplane mode. The failure reaches the user before the architecture becomes visible. Unlike a web server that can re-evaluate on each request with a live connection assumed, an iOS app has no guarantee of connectivity. A feature check should run in memory so it never has to wait for the network.
Remote evaluation adds latency to each check and makes the remote service a point of failure. Local evaluation instead downloads flag definitions upfront and evaluates them in-process, making sub-millisecond checks possible. For consumer iOS, this is the correct default. Network access updates the information available to the app rather than becoming a prerequisite for every decision.
The binary release model makes that distinction consequential. Replacing an unguarded change shipped through the App Store takes another review cycle, so keeping a release safe must involve more than shipping another binary. Flags provide control over guarded behavior within the version already installed. That control is useful only if the app can evaluate it under the conditions in which people actually use their phones.
The four flag types and why each one demands different lifecycle and ownership rules
Local evaluation answers where a decision happens, but not who owns it or when it should disappear. Those questions depend on the flag’s purpose. Release, experiment, operational, and permission flags differ in how they need to be evaluated and when they should be retired. Treating them as interchangeable entries in an undifferentiated store hides those differences until deletion becomes difficult.
Release flags gate features until they are ready for all users. They belong to the feature team and are short-lived, with deletion expected after full rollout. Experiment flags instead support A/B and multivariate tests, with ownership shared by product and engineering. Their lifetime follows the experiment’s statistical validity window. A completed rollout and a completed experiment are different events.
Operational flags are kill switches and controls over production behavior that stay in place longer. They require explicit engineering ownership and a review cadence, even when there is no immediate reason to remove them. Permission flags are the category where indefinite persistence is expected and acceptable. Longevity does not remove accountability for the decision.
These distinctions belong in the architecture. A flag definition must say enough about why the flag exists for its owner to know whether to remove, review, or keep it. Otherwise, the same convenient mechanism becomes a collection of conditions that no one knows how to retire.
A Swift-native flag system: typed keys, protocol injection, and environment-based composition
Swift can make flag definitions precise at the point of use. A generic FeatureFlagKey<Value> associates a key with its value type, so a FeatureFlagKey<Bool> and a FeatureFlagKey<String> cannot be consumed interchangeably. In a compact illustrative sketch, let newCheckout = FeatureFlagKey<Bool>("newCheckout", defaultValue: false) defines a true-or-false key with a fallback. A matching service read, such as let enabled = featureFlags.value(for: newCheckout), preserves that type. Assigning a string-valued read to a true-or-false variable becomes a compile-time error.
The service behind those reads should be protocol-first. Feature code depends on the evaluation contract rather than a particular SDK implementation, which keeps the architecture independent of the flag provider. This boundary also makes substitution straightforward in tests. The production service and a test implementation answer the same typed requests without forcing feature code to know which one it received.
SwiftUI’s environment provides the composition point. An illustrative declaration, @Environment(\.featureFlags) var featureFlags, gives a view access to the injected service. Tests and Xcode Previews can replace it by setting a different environment value at the root, without a singleton or mocking framework.
Evaluation should then stop at the appropriate view boundary. A container resolves the flag and passes a concrete value to its children instead of scattering flag-service calls throughout leaf views.
Why modular SPM architecture is the load-bearing structure that makes flags work at scale
In a monolithic target, even a well-designed flag service can be tangled up in feature dependencies and files that several teams must edit. Swift Package Manager packages give each feature a clear boundary. With dependency rules enforced, one feature’s flag evaluation does not accidentally depend on another feature’s state, and teams can work without competing over shared flag definitions.
Just Eat Takeaway’s 2026 architecture refresh provides the relevant rule. Feature modules do not depend on other feature modules. Shared needs move into a lower-level Foundation module or are coordinated through an upstream abstraction at the App layer. JET kept that rule from 2019 as the number of modules roughly doubled. The durable choice was the dependency constraint.
The refresh also exposed the limits of those labels. CountdownTimer was a UI component needed by two domain modules, but the old three-group model gave it no valid home. Labels such as “shared” and “cross-domain” described topology without explaining purpose. Categorizing modules by role allowed their positions in the graph to follow from clear rules instead.
A flag evaluation module follows the same logic. It belongs near the bottom of the dependency graph, where feature modules can depend on it without creating a dependency in the reverse direction. This gives the protocol boundary structural force. Modular Swift Package architecture also offers build-time reductions of 40–70% on large iOS codebases, reinforcing the benefit of isolation as the project grows.
Offline resilience and layered storage as production requirements, not defensive extras
Module boundaries govern dependencies, but runtime behavior needs a separate contract. A flag service that blocks or returns an error solely because the device is offline remains a fragile remote configuration call. The app must work offline as part of everyday use, as well as when unusual failures occur.
The storage model has three layers with distinct jobs. An in-memory cache supports sub-millisecond evaluation during runtime. Persistent local storage, using UserDefaults or a lightweight database, preserves available values across cold launches without connectivity. Safe compiled-in defaults provide the final fallback when no stored value is available. Each layer addresses a different point at which access to flag data can fail.
The fallback must preserve safe product behavior. In this context, failing open means returning the safe default rather than allowing evaluation failure to block the app. It does not mean enabling every guarded feature. The default belongs to the feature’s safety decision, so a user in a subway tunnel or on a long-haul flight does not encounter broken behavior merely because a server is unreachable.
Storage should be injected in the same way as evaluation. Tests receive an in-memory stub, while production receives the persisted implementation. The evaluation logic depends on the storage contract. This makes offline behavior testable without coupling the feature’s decision logic to persistence details.
Flag sprawl: how stale flags become technical debt and how to prevent it systematically
Correct evaluation does not prevent a flag system from accumulating debt. Stale, unowned flags leave dead code that is harder to test and debug, especially when nobody can establish whether a branch is still needed. Automated tooling that detects and removes obsolete flag code addresses the volume that individual teams cannot reliably manage by hand.
Removal is not the only lifecycle risk. Reusing an old flag name can reactivate dead code and trigger unintended behavior, so a familiar name is not evidence that its previous meaning has disappeared. Across platforms, this failure mechanism follows from leaving obsolete branches reachable while allowing the control that selects them to acquire a new purpose.
Centralized evaluation makes that risk easier to audit. A single owned function or class can expose a decision such as featureGates.showNewCheckout(), called at the relevant feature boundary instead of replaced by inline SDK calls across many files. Deletion then has a defined place to begin. The container pattern also keeps that cleanup from spreading unnecessarily through presentation code.
Release flags need a feature-team owner and a target deletion date at rollout, while experiment flags expire with the experiment. Operational flags need scheduled review. Permission flags can persist indefinitely, but their ownership remains part of the record.
Applying the same flag discipline to AI feature rollouts on iOS
AI-powered features bring new rollout decisions, but the basic flag categories stay the same. Local evaluation and offline resilience are at least as important here as for conventional features. A rollout decision should not gain a network dependency simply because the feature it controls uses AI.
Apple’s Foundation Models framework provides access to on-device inference, while App Intents exposes app capabilities to AI agents. Apple’s Private Cloud Compute supports tasks that need greater capacity than on-device processing can provide. These capabilities place AI within the iOS platform layer. The app’s release controls thus need to handle AI surfaces in the same architecture as its other features.
A locally evaluated experiment flag can gate an AI-powered feature for a fraction of users. An operational kill switch provides a separate control over that feature’s availability in production. The distinction is deliberate and useful. The experiment owns the test’s lifetime, while the operational flag serves the longer-lived need to control behavior when conditions change.
AI-generated Swift code adds another reason to preserve clean boundaries. Code may compile while using deprecated SwiftUI modifiers or superseded patterns, creating debt that type checking alone does not catch. Flags do not correct that code. However, isolated feature boundaries and centralized gates make an implementation easier to contain and replace without broad refactoring.
What consumer-scale engineering organizations actually require from their iOS flag infrastructure
Consumer-scale organizations need ownership and coordination as much as an evaluation API. App Store review latency constrains how quickly a replacement binary can reach users, global audiences make offline operation a baseline requirement, and high daily active usage makes evaluation performance part of product performance. These pressures meet inside the same infrastructure. Treating flags as incidental configuration leaves their combined cost with individual feature teams.
That cost becomes harder to manage as the team grows. A handful of engineers may remember which flags are live, why they exist, and who intends to remove them. A larger organization cannot depend on that memory. Centralized evaluation, typed keys, and records that name each owner keep the information that teams lose when they rely on memory, while module boundaries let teams work on their own.
The leadership decision is when to establish those constraints. Protocol injection, layered storage, modular packages, and lifecycle governance are not speculative optimization for a distant scale. They govern how the next feature is tested, how the next flag is retired, and how the next engineer understands the codebase. AI capabilities add to that workload without changing the underlying obligation.
The cost of deferring these decisions compounds. Once flag checks, storage assumptions, and unowned branches spread through a consumer app, establishing discipline also requires undoing existing coupling. Making these decisions early lets the organization add engineers and capabilities without having to rebuild the infrastructure that controls their release over and over.