A/B Testing Infrastructure for Native iOS Consumer Apps
Solving iOS A/B testing requires infrastructure, not just an SDK.
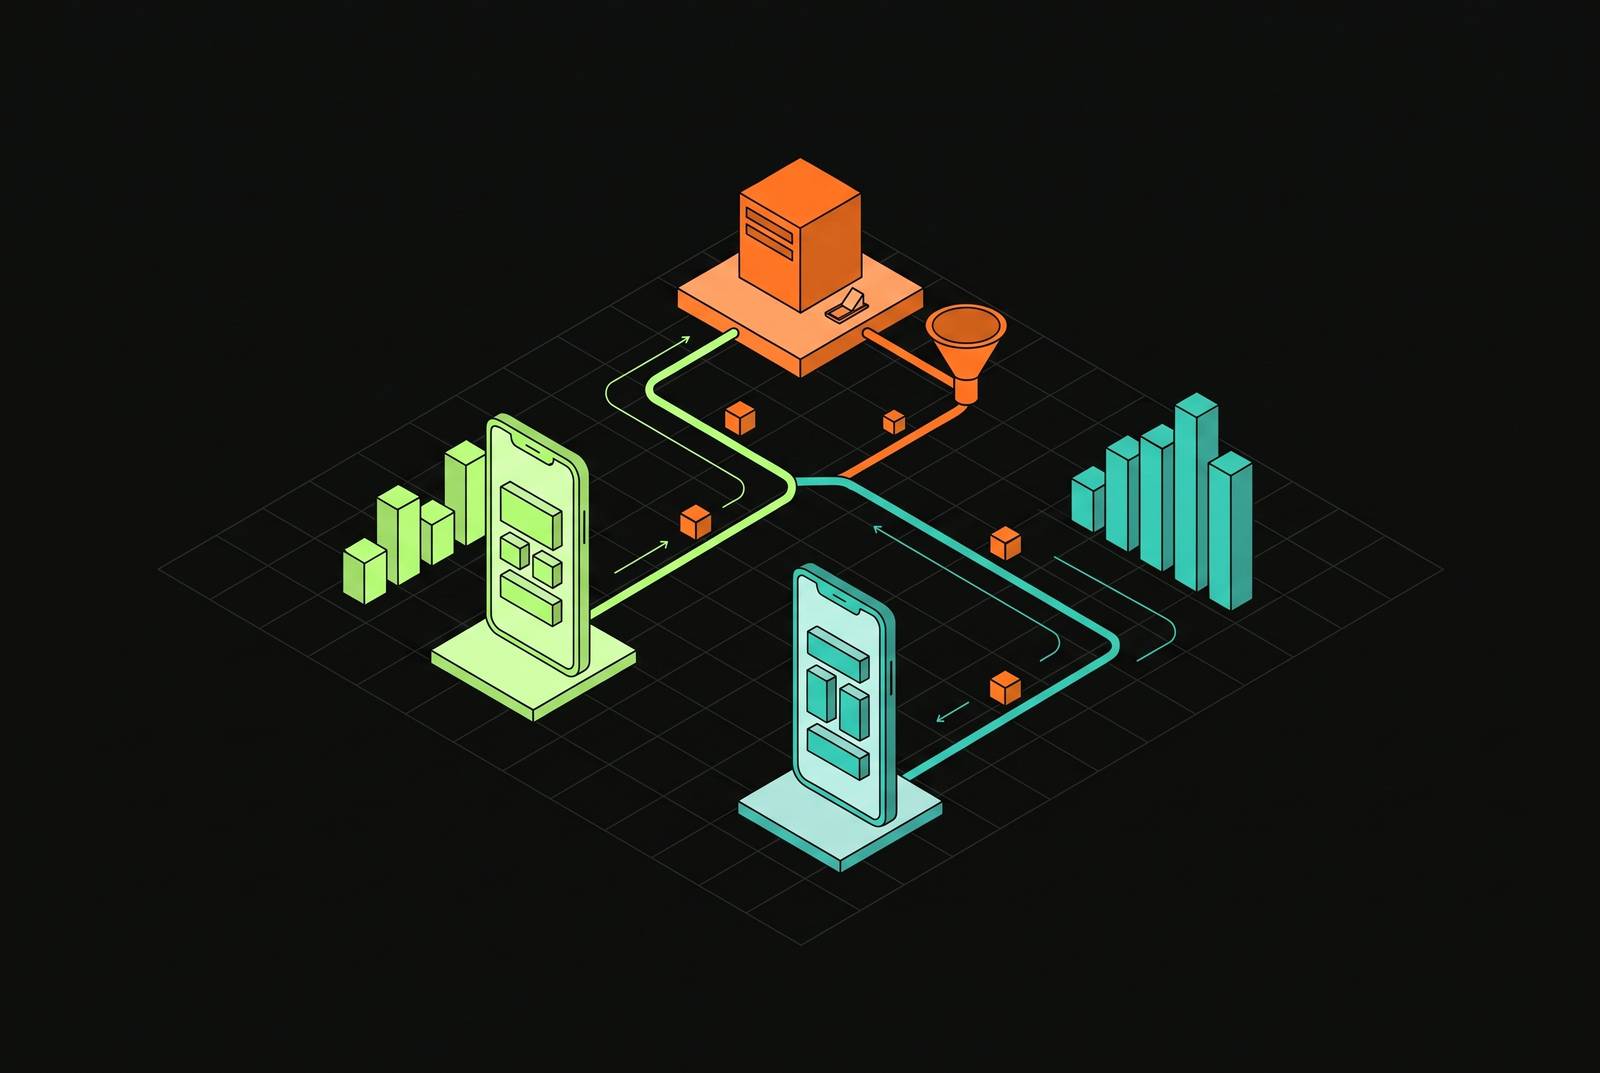
A/B testing infrastructure for native iOS consumer apps requires more than an experimentation SDK. App Store review, App Tracking Transparency restrictions, and offline use force architectural decisions about delivery, identity, and measurement. Reliable experiments depend on resolving those constraints as one system, then operating that system with the same discipline as other production infrastructure.
Why A/B testing on iOS is an architectural problem, not a tooling problem
Most iOS teams treat A/B testing as a product-team concern and reach for a third-party SDK. The first serious experiment exposes the limits of that approach. Variant logic may be trapped in unreviewed code, identity may depend on an unavailable tracking signal, or evaluation may require connectivity the device does not have. These are infrastructure failures before they are experiment-design failures. An SDK cannot decide how the app should behave at those boundaries.
Each constraint creates a different architectural obligation. App Store review requires separating code deployment from behavior activation, while App Tracking Transparency (ATT) makes deterministic assignment without IDFA a first-class requirement. For offline use, both configuration and assignment must work on the device. Web patterns transfer poorly to this environment. Server-side assignment, redirect tests, and real-time flag evaluation cannot simply be transplanted into a native app without resolving startup behavior and persistence. Otherwise, users see flicker or get moved between variants, and teams have experiments they cannot launch.
How remote config becomes the delivery layer and why it must be treated as infrastructure
Remote config breaks the coupling between a reviewed binary and the behavior it activates. It can choose among capabilities already shipped, but it cannot add native variant logic that is missing. Without that separation, experiment iteration follows App Store review cadence. Teams also use feature flags beyond experiments, with release toggles to hide unfinished work, ops toggles to respond to incidents, and permission toggles for subscription tiers or user types. An experimentation system therefore extends a feature flag system.
The app should fetch configuration on launch, cache it locally, refresh it in the background, and fail gracefully without blocking startup. Persisting last-known flags in UserDefaults or an equivalent store gives the app a valid configuration state without connectivity. If the first render instead waits for fresh flags, the network becomes a launch dependency. If rendering starts before the configuration is settled, a late response can cause flicker.
The implementation deserves the same architectural rigor as a backend contract. Raw string keys resolved at call sites scatter experiment logic and make removal difficult. A typed enum or value-type wrapper makes that contract explicit and lets the compiler catch misuse. In SwiftUI, injecting the flag resolver through the environment lets views read values without threading dependencies through initializers or view models. This keeps delivery concerns out of the view hierarchy’s plumbing.
The architecture must also support the rollout process. Small-percentage releases, segment targeting, beta access for power users, and explicit control groups require more than a boolean switch. Removal should be as easy as addition. Otherwise, completed experiments leave dead branches that make the app progressively harder to reason about.
Solving user assignment consistency under ATT restrictions and offline conditions
A cached flag tells the app what experiments exist, but not which variant a user belongs in. That decision needs a deterministic, locally computed mechanism independent of IDFA and live network access. ATT makes IDFA unavailable for users who decline tracking. Randomly rebucketing those users in each session would expose them to a mix of variants and spoil the results. The user’s identity must stay the same without becoming a cross-app tracking signal.
An anonymous ID that the app generates and keeps serves as that bucketing key. Where persistence across reinstalls on the same device is appropriate, storing the ID calls for replacing UserDefaults with Keychain. Hashing it against the experiment key produces a repeatable assignment without a round-trip. Cached configuration and stable identity then allow evaluation offline. Reconnecting does not itself require a new assignment or a mixed-variant session.
This logic needs tests independent of the UI. An ID change or bucketing update can move a user across a variant boundary even when every screen renders correctly. Their data then no longer represents consistent exposure to one treatment. The defect is one of correctness. Assignment tests must establish that the same inputs continue to produce the same bucket under the conditions the app supports.
Instrumenting metrics correctly so experiment results align with business outcomes
Consistent assignment establishes exposure, but interpreting that exposure requires correct instrumentation. Events fired before assignment is confirmed, duplicated by background fetch re-fires, or attached to the wrong lifecycle phase silently corrupt the dataset. A button tap also answers a different question from a subscription start. The event contract must reflect the business outcome. Of the surfaces where consumer iOS apps run experiments, paywall and onboarding experiments have the greatest effect on revenue, so the infrastructure that measures them is critical in production.
Analysis cannot repair every defect in that contract. Testing many metrics simultaneously creates opportunities for apparently significant results by chance, so the primary metric must be defined in advance and secondary metrics treated as exploratory. Peeking before the predetermined sample size is reached also inflates false positives. Sequential testing can address that problem when the platform supports it. Separately, novelty effects can last days to a few weeks, so retention and revenue tests need enough time to capture behavior beyond the initial response.
Measurement consistency extends beyond the experiment report. Amplitude identifies an advantage in using the same events and metrics for experimentation and product analytics, with warehouse connections supporting consistent definitions. Separate pipelines can leave business dashboards and experiment reports telling different stories. That disagreement is an engineering concern. The metric layer must connect the treatment being evaluated to the outcome the business actually uses.
What the leading platforms do well and where each creates iOS-specific trade-offs
The useful comparison concerns delivery, assignment, initialization, and measurement ownership. Every option leaves integration decisions with the team. The iOS constraints determine which of those decisions require the most scrutiny.
Amplitude Feature Experimentation combines analytics and experimentation, using the same events for experiment results and product analysis. It also connects to data warehouses and offers high-performance SDKs and real-time segmentation. The fit is strongest when teams want unified metrics without a custom pipeline. On iOS, SDK weight and initialization still need evaluation against the requirement that experimentation never block launch.
Firebase A/B Testing is a good fit for teams already in the Google ecosystem that want to run simple flag-based experiments. Its free tier and Remote Config support feature toggles without app updates, although integrations with other analytics tools are limited. Firebase’s iOS documentation describes cached fetched values and immediately available in-app defaults. Those provide fallback behavior. Stable assignment and startup behavior remain integration responsibilities.
Optimizely Feature Experimentation lets enterprises run full-stack testing across their mobile clients and servers. It fits large organizations that run their web and mobile experiments from a single dashboard. Detailed measurement requires a separate analytics tool. That separation can reintroduce conflicting metrics unless the team invests in integration.
LaunchDarkly emphasizes feature flag management, deployment control, and developer workflows, with basic A/B testing and limited experimentation analytics. Its strengths map to release and ops toggles. Engineering-led teams prioritizing safe deployment and controlled rollouts fit that model. Teams still need a separate measurement layer for revenue experiments.
Apptimize, now owned by Airship, takes a mobile-first approach with visual editors and drag-and-drop experiment creation for non-technical users. Its orientation is marketing and engagement. With visual editing, engineers can do less of the work on simple UI experiments. It does not remove the need for consistent assignment or correct instrumentation.
AB Tasty combines mobile A/B testing with personalization, AI-driven content optimization, and drag-and-drop interfaces. Its focus includes e-commerce and marketing. Personalization is relevant to experiments involving generated content, but that does not establish an on-device implementation. The platform’s orientation also needs to fit the consumer app’s architecture.
The build-versus-buy decision is therefore not binary. Most production iOS teams use a vendor for assignment and flag delivery while owning metric instrumentation because business definitions are specific to their data model. Behavioral analytics can complement that arrangement by explaining both which variant won and why behavior changed. Buying delivery does not transfer responsibility for the meaning of the result.
App Store Product Page Optimization as a separate, complementary testing surface
Apple’s Product Page Optimization (PPO) operates in App Store Connect, outside the in-app delivery and assignment system. Its testing scope is limited to icons, screenshots, and preview videos. Google Play Store Listing Experiments also supports text testing. PPO is a distinct acquisition surface.
Its review constraints differ from in-app flag activation. Icon variants must already be in the binary so the store icon matches what appears on the home screen after installation. That requires an app submission, though not a separate submission for each included variant. All treatments must pass Apple review before they can launch. Up to three treatment variants can run against the control, and meaningful tests typically need at least a week to absorb weekday-versus-weekend variation at lower install volumes.
SplitMetrics and Storemaven let teams test outside the store before launch or with more traffic, and Apple Search Ads gives them another place to test creatives before PPO. None makes store results flow automatically into in-app analytics. Teams must decide how to link conversion data to what users do next.
For in-app iteration, technology choice changes a different constraint. Native releases pass through App Store review, while React Native with Expo enables faster delivery through OTA updates. That agility comes with slower startup and higher memory use than native, with consequences for onboarding and paywall experiments in the opening seconds of a session. Casey favors a native programming language and SwiftUI as a modern base for building iOS products. React Native relaxes release lag, but relocates complexity into dependencies, platform quirks, maintenance, and a hybrid native/JS implementation that still needs ATT-compliant assignment, offline consistency, and correct metrics.
Where on-device LLMs open a new class of experiment variant in iOS 26
The Foundation Models framework in iOS 26 introduces on-device LLMs that run locally by default and keep user data on the device. Their latency profile makes real-time personalization viable within experiment variants. The treatment can therefore include model-generated output as well as a static flag-selected interface. This expands what the assignment system is selecting. It now chooses a behavior whose content may depend on individual context.
App Intents provides the route for agentic workflows. A variant can represent different screens, agent behavior, task decomposition, or model-driven personalization. This connects agent architecture directly to experimentation architecture. Local inference is also compatible with ATT-compliant assignment because personalization need not depend on cross-app tracking signals.
Dynamic content introduces another consistency requirement. A stable bucket alone does not establish a reproducible treatment if the generated variant changes across sessions. The seed or model state responsible for an output must remain stable for the same user where that stability defines the treatment. Assignment consistency therefore extends into variant content. The infrastructure must account for both the selected strategy and the model-generated parameters it produces.
The operational practices that determine whether the infrastructure actually produces reliable decisions
To run this infrastructure reliably, teams must choose the primary metric, target cohort, and expected effect size before each experiment. These choices establish what result the test can interpret. Low-traffic apps should target larger effects or defer testing until traffic grows rather than attempt to detect small changes with insufficient data. Correct infrastructure cannot compensate for an underpowered experiment.
Results also need cohort-level analysis as a standard step. An aggregate neutral result can conceal gains in one group and losses in another. Concurrent experiments require similar care across onboarding, paywalls, feature design, and push. The infrastructure must isolate assignment, while the team decides which tests can run together and which need sequencing. At conclusion, flag removal should be a scheduled engineering task with a deadline.
Casey’s Lululemon experience illustrates an organizational structure suited to this work. A Staff iOS Engineer owns foundational infrastructure used across squads, including implementation standards and the tech debt roadmap. The architecture establishes the correct system to build, but careless experiment operation can still turn it into a source of bad decisions. Ongoing engineering discipline is the multiplier.